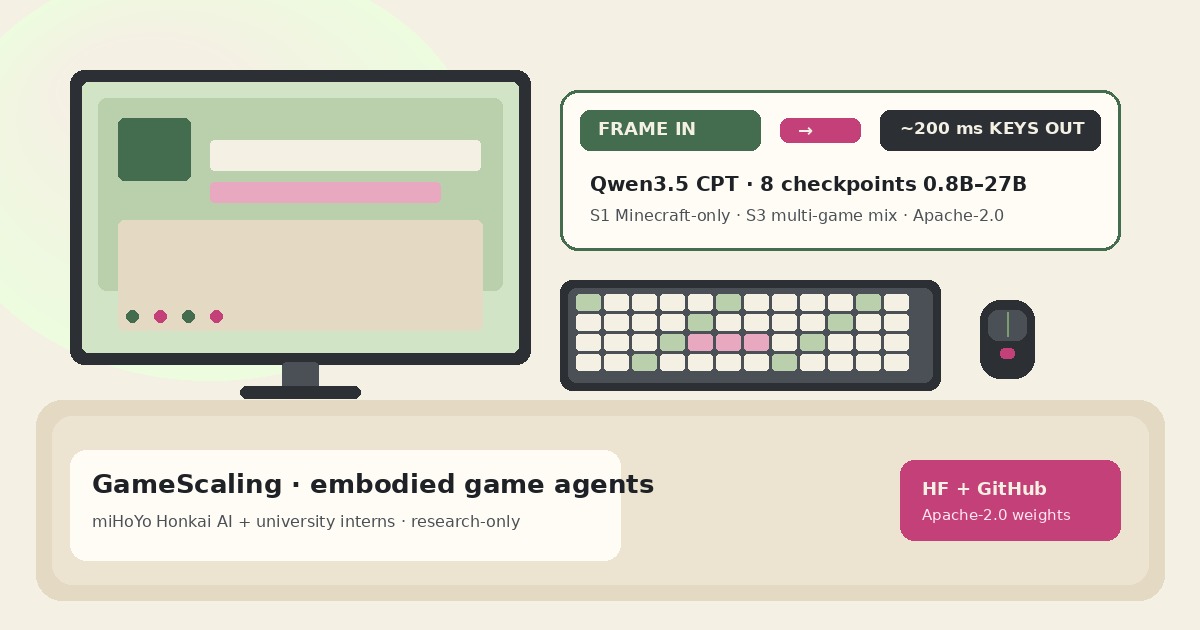
GameScaling is not another chat checkpoint with a gaming skin. It is continued pre-training of Qwen3.5 vision-language backbones on keyboard-and-mouse gameplay so the model can act as an embodied game agent: take the current screen (plus a short history of frames and actions) and return the next slice of controls. Chinese coverage from IT之家 (Oct 22, 2026) and the English project materials line up on the same core loop and release shape.
What it does in one decision step
Each model call is designed for realtime-ish interaction. Per the Hugging Face / GitHub docs:
- Input: current game frame, plus a short history of past frames and the actions already taken (default history length is five turns in the shipped client).
- Output: the next ~200 ms of keyboard and mouse control — six steps of 33 ms each, plus one mouse movement and scroll amount for the whole chunk. The model may optionally “think” before emitting the action tags.
- Serving path: inference client, system-prompt template, action parser, and example scripts ship with the repo; checkpoints are meant to be served with vLLM (docs mention testing around vLLM 0.17).
IT之家 notes the same ~200 ms / 6×33 ms design and that runtime depends on model size, hardware, and load — not a fixed “always realtime” guarantee.
Four sizes — 0.8B, 2B, 9B, 27B — each with an S1 and an S3 mix. S1 is Minecraft-only; S3 is a multi-game mix with Minecraft at 27%. All eight released checkpoints use 1,600 hours of gameplay data. bf16 weights: roughly 2.2 GB / 5.4 GB / 18.8 GB / 54.7 GB. 0.8B–9B fit one GPU; 27B needs two GPUs with tensor parallel, per the HF card.
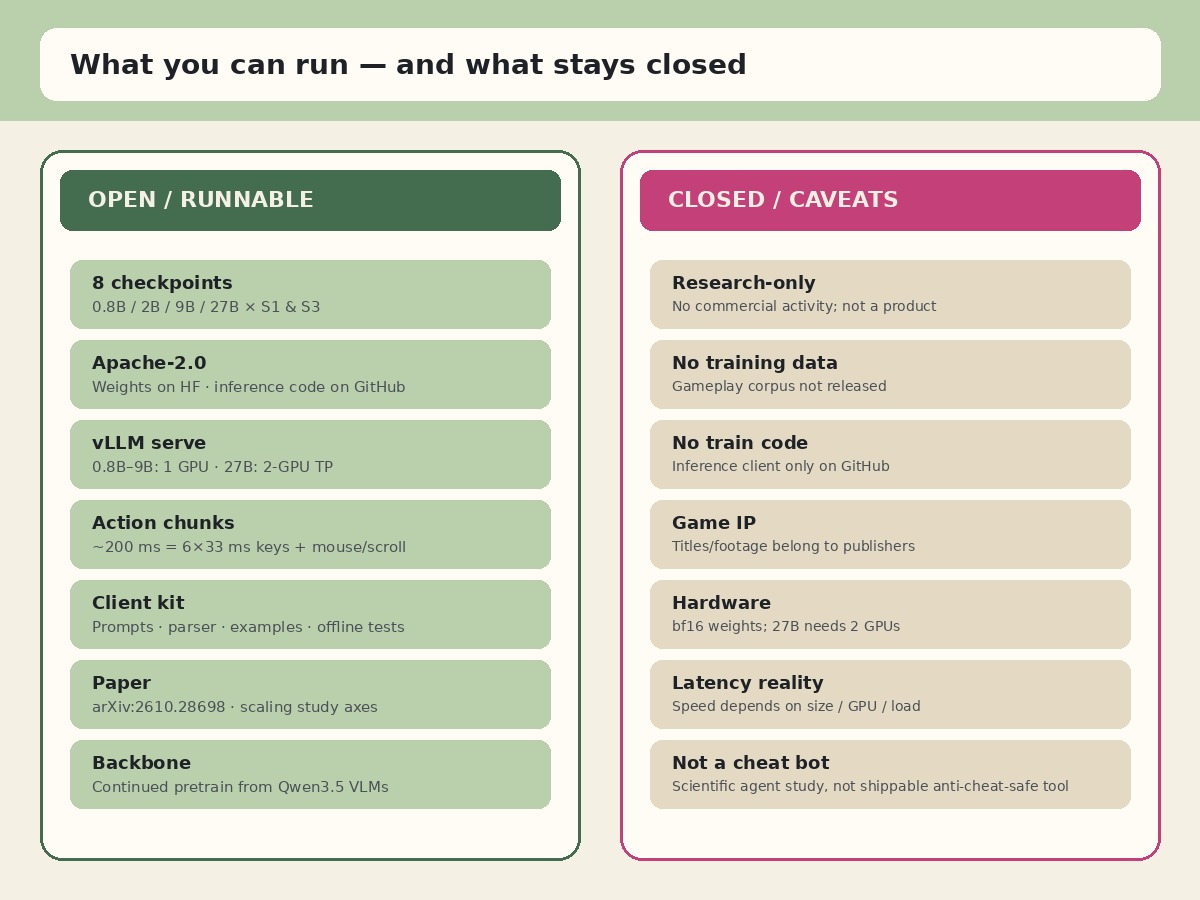
Open: Apache-2.0 weights + inference code. Closed: training corpus, training code, and any commercial use of the project.
Can you actually run it?
Yes, for inference research — if you have the GPUs and you bring your own legal game environment. The collection lives under Hugging Face THUSI-Lab/GameScaling; code is on GitHub THUSI-Lab/GameScaling; both weights and code are Apache License 2.0 (continued from Apache-2.0 Qwen3.5). The client can talk to a local vLLM server; offline unit tests cover prompts and action parsing without a GPU.
What you do not get: the training corpus, training code, or a turnkey “play any commercial title” product. The project page and README state that GameScaling is a purely scientific research project with no commercial activity, that gameplay data is not released, and that game titles, footage, and trademarks belong to their publishers — Apache-2.0 covers only the team’s weights and code.
What the paper is trying to change
The paper — Scaling in Games: Continued Pre-Training for Embodied Agents in Diverse Virtual Worlds (arXiv:2610.28698) — asks whether the familiar scaling story (more data, more diversity, bigger models) carries from one physical world into many virtual ones with different visuals, dynamics, and controls. The study reports 120 training configurations across four sizes (0.8B–27B), six data budgets (50–1,600 h), and five mixtures (S1–S5); the training corpus spans 80 games. Released public checkpoints are the 1,600 h S1 and S3 pair at each size — not the full S1–S5 grid.
Headline research claims from the project page (not independent benches): more data helps in-corpus play; diversity helps transfer to related worlds with limited gains on distant ones; larger models learn faster but, under single-world training, generalize worse to distant worlds; and GameScaling’s step latency is cited in the 0.13–0.69 s range versus frontier models taking 4–24 s per step in their comparison framing — which is why the authors emphasize real-time (world does not pause) settings. Treat those latency and score figures as paper/project claims until you reproduce them.
Honest caveats
- Research-only — no product, no paid license, no commercial activity with this release.
- No training data release — you cannot retrain or audit the corpus from the open dump.
- No training code — inference client and serving scripts only.
- Game IP stays with publishers — weights/code Apache-2.0 does not grant rights to Minecraft, Doom, or any other title.
- Hardware is real — bf16 checkpoints; 27B is a two-GPU serve; smaller sizes still want a serious GPU for comfortable realtime loops.
- Not an anti-cheat-safe bot — this is an embodied-agent research stack. Running agents inside live online games can violate ToS and fair-play rules; that is outside the project’s stated scientific scope.
Bottom line for overseas ML and games researchers: GameScaling is a rare open set of keyboard/mouse VLMs with a clear frame→action interface, scaling-law paper, and runnable vLLM path. Download the Apache-2.0 checkpoints if you care about embodied control and realtime agent latency — and keep the research-only / no-data / publisher-IP fence in view the whole time.