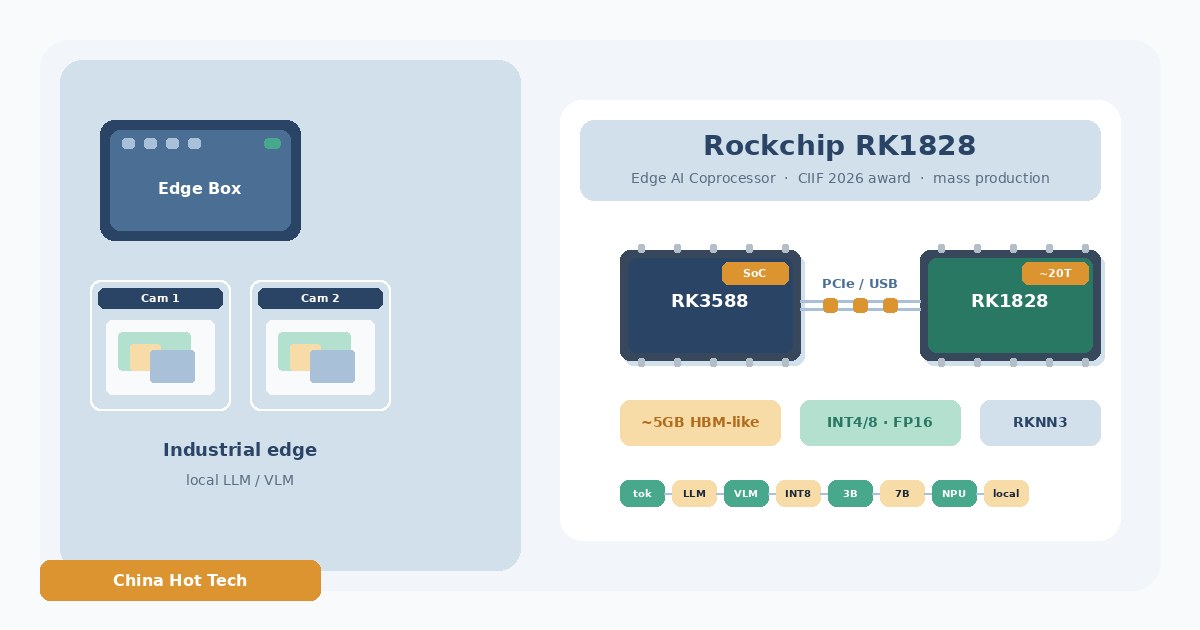
Most “edge AI” upgrades still mean ripping out a box and buying a new SoC. Rockchip’s pitch with RK1828 (RK182X family flagship) is different: keep the host that already runs video ingest, I/O, and control — then bolt on a dedicated AI card for generative multimodal inference. Chinese industry coverage around the 2026 Shanghai CIIF / 国芯展 frames that split as the practical path for factory inspection, site patrol, kitchen/campus security boxes, and robot stacks that already sit on RK3588-class hardware.
What the chip claims to be
Partner and press writeups (万物纵横, Rockchip’s own WeChat as carried by 同花顺, AI123) consistently describe RK1828 as an AI-only coprocessor: it does not run the OS. Headline numbers that appear across those pieces:
- ~20 TOPS NPU (INT8 framing in the same coverage)
- ~5GB high-bandwidth on-chip DRAM — also described as 3D-stacked / near-memory / “存算一体” bandwidth relief for LLM decode. Treat the packaging language carefully; the shared claim is on-die high-bandwidth memory sized around 5GB, not a public JEDEC datasheet we audited here.
- Mixed precision: INT4 / INT8 / FP16 (one partner note also lists BF16)
- Host link: Rockchip WeChat / 同花顺 cite PCIe 2.0 and USB 3.0; one ODM-oriented 万物纵横 piece instead says PCIe 3.0 — flag the mismatch and prefer the WeChat wording until a public datasheet settles it.
- Local models: adapted 3B / 7B LLM and VLM on a single card; multi-chip cascade claims reach about 27B parameters. A separate 万物纵横 box note also mentions up to ~8B in some dual-card configs — press, not independent benches.
- Software: RKNN3 SDK, with vendor claims of >15% LLM decode uplift vs prior tooling, plus an OpenAI-compatible API path so integrators can reuse familiar client patterns.
- Throughput: vendor ~102+ tokens/s on a 3B-class model (万物纵横).
Rockchip and partners say the part is already in scale mass production, with demos and reference edge boxes shown at CIIF for industrial robots, machine vision, and edge industrial control.
There is no confirmed global retail SKU. The path today is China ODM / embedded partners (core boards, industrial motherboards, edge boxes) — names that show up around Rockchip’s industrial wall include Forlinx, MYIR, Advantech, Firefly, Qiyang, EmbedFire, and Rocktech (瑞迅). Overseas teams typically buy through China supply / local distributors, not Amazon or Digi-Key. Treat “available” as design-in via those channels, not a drop-in M.2 card on a US storefront.
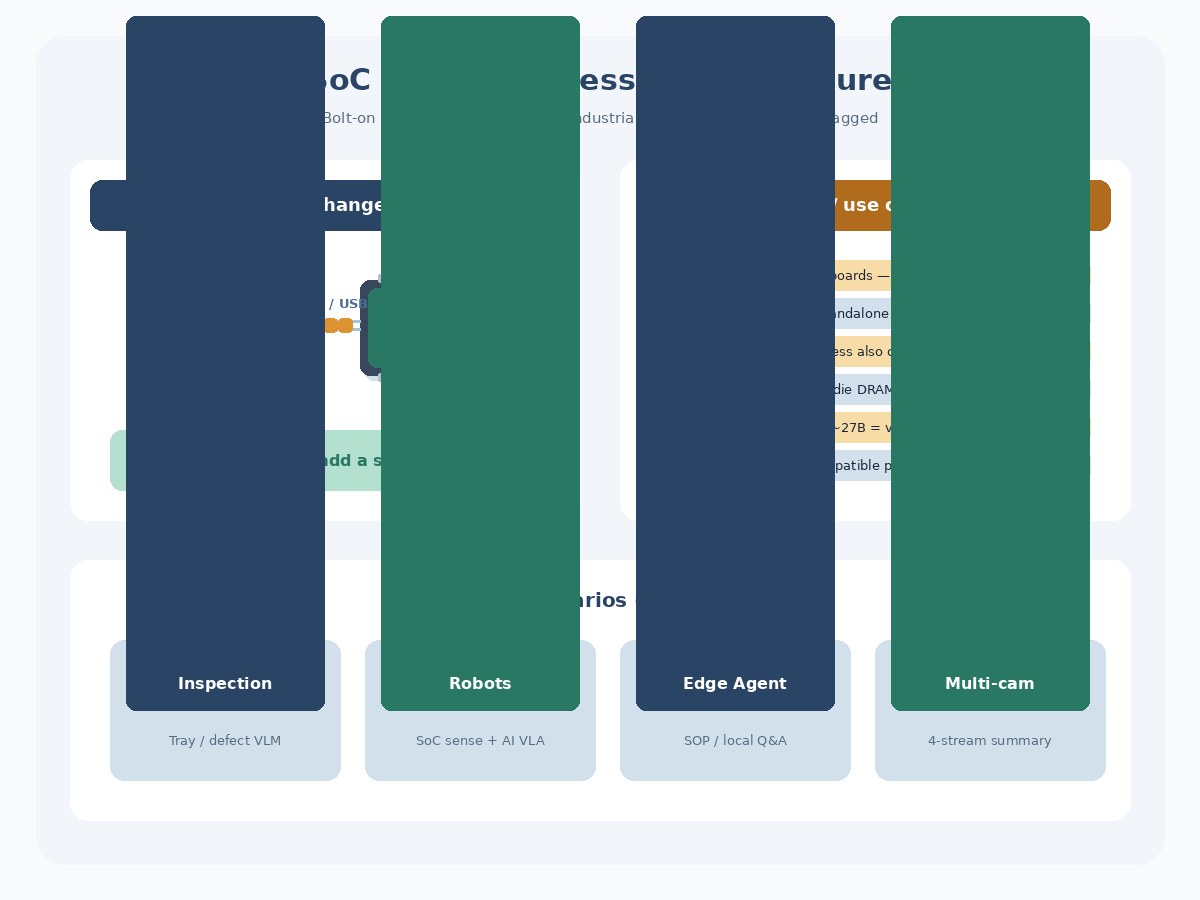
Architecture vs caveats. Asterisked TOPS, memory packaging, token rates, cascade sizes, and demo timings are vendor or Chinese press claims.
SoC + coprocessor, not a bigger monolith
The architecture story is the product. On a typical dual-chip edge box, RK3588 (or RK3576) keeps camera ingress, preprocessing, peripherals, and UI; RK1828 takes LLM / VLM / VLA inference so the host NPU and system DRAM are not fighting the model. 万物纵横’s companion note on the CIIF booth sketches the arithmetic for one popular combo: RK3588’s own ~6 TOPS NPU plus one RK1828 (~20 TOPS) ≈ 26 TOPS system total; dual RK1828 cascade ≈ 46 TOPS — again, INT8 marketing math from a partner blog, useful as a sizing map rather than a lab result.
For robotics, Rockchip’s WeChat framing is explicit: the SoC owns sensing, control, navigation, and multi-sensor fusion; the coprocessor owns language, vision-language, and vision-language-action (VLA) policy inference, plus supporting models such as speech, embedding, and reranker. Rocktech’s post-show writeup describes AMR / patrol stacks where RK3568/RK3588 handle motion while an RK1828 card runs the VLA path — the same “keep the chassis, add a brain card” upgrade story aimed at warehouses and campus robots.
What industrial demos are actually showing
CIIF coverage is heavy on factory-floor narrative. 财闻 / 同花顺 field reporting cites a Tray-disk inspection demo claiming 490 chips checked in 25 seconds on an RK1828-based setup — a booth claim. Partner materials list multi-camera concurrent analysis, video summarization, SOP verification, local knowledge-base Q&A, and end-side agent task planning for weak-network or offline plants. One 万物纵横 box piece claims four-stream analysis with content summary responses as fast as ~0.5 s — press demo timing, not a third-party latency study.
The strategic angle for overseas edge and robotics engineers is less “another Chinese NPU” and more modular upgrade of the RK3588 installed base. If your China ODM already ships RK3588 boxes for HMI, NVR-style analytics, or AMR brains, an RK1828 side card is how those vendors say they add offline 3B/7B multimodal without a full board respin. That is a different procurement conversation from buying a new Jetson-class module or waiting for a next-gen monolithic SoC.
Software surface and CRA footnote
RKNN3 plus an OpenAI-compatible API path is the developer hook Chinese coverage keeps repeating: lower the cost of porting chat / VLM clients that already speak OpenAI-style HTTP. Expect Linux and Android dual-system support in the partner kits. Separately, Rockchip’s CIIF messaging notes EU Cyber Resilience Act (CRA) vulnerability-reporting obligations that applied from 11 Sep 2026, with an RKPSIRT process positioned as SDK/chip-level support for industrial terminals that must ship into Europe — relevant if your product roadmap already includes CRA evidence packs.
Honest caveats
- Coprocessor, not a host — you still need an SoC (typically RK3588 / RK3576 family) and a board that exposes PCIe or USB to the AI card.
- Vendor / press numbers — ~20 TOPS, ~5GB on-die DRAM, 102+ tok/s on 3B, cascade ~27B, Tray 490/25s, 0.5 s multi-cam summary, and “>15% decode uplift” are Rockchip or partner claims from Chinese coverage; not independently measured here.
- Memory wording — “3D-stacked,” “near-memory,” “百GB/s-class bandwidth,” and “存算一体” appear in press; treat as vendor marketing until a public datasheet defines the memory stack.
- PCIe generation mismatch — WeChat / 同花顺 say PCIe 2.0 + USB 3.0; at least one partner blog says PCIe 3.0. Design-in teams should confirm the physical interface on the actual module.
- China-centric supply — mass production and ODM kits are real in the China industrial channel; there is no confirmed global catalog part with Western FAE coverage comparable to NVIDIA or Qualcomm edge lines.
- Model zoo reality — “supports 3B/7B” means adapted / quantized models under RKNN3, not arbitrary Hugging Face checkpoints at full precision.
Bottom line: RK1828 is Rockchip’s clearest move yet to sell bolt-on local generative AI for the huge installed base of Chinese industrial SoC boxes — award-backed at CIIF 2026, in mass production per vendor statements, and already wrapped by ODM reference designs. For overseas edge and robotics teams, the signal is architectural (SoC keeps control; AI card takes the model) and commercial (China ODM design-in), not a claim that you can order a retail accelerator tonight.